Our Dynamo post is now a case study in the NVIDIA Dynamo docs
NVIDIA just added our Viettel Cloud Tech Blog post to the NVIDIA Dynamo docs as a case study, one of 8 alongside Amazon Ads, Pinterest, Cognition, Prime Intellect, DigitalOcean, Photoroom and H Company.
The post covers how we serve multiple LLM families on one H200 fleet with NVIDIA Dynamo, a component of NVIDIA DSX OS.
I wrote it with Doan Thinh Vo, and we did the work together with Henry Ma, Nan Gu, Kuldeep Sharma, Tao Liu, Azman Salleh and Que Nguyen from NVIDIA.
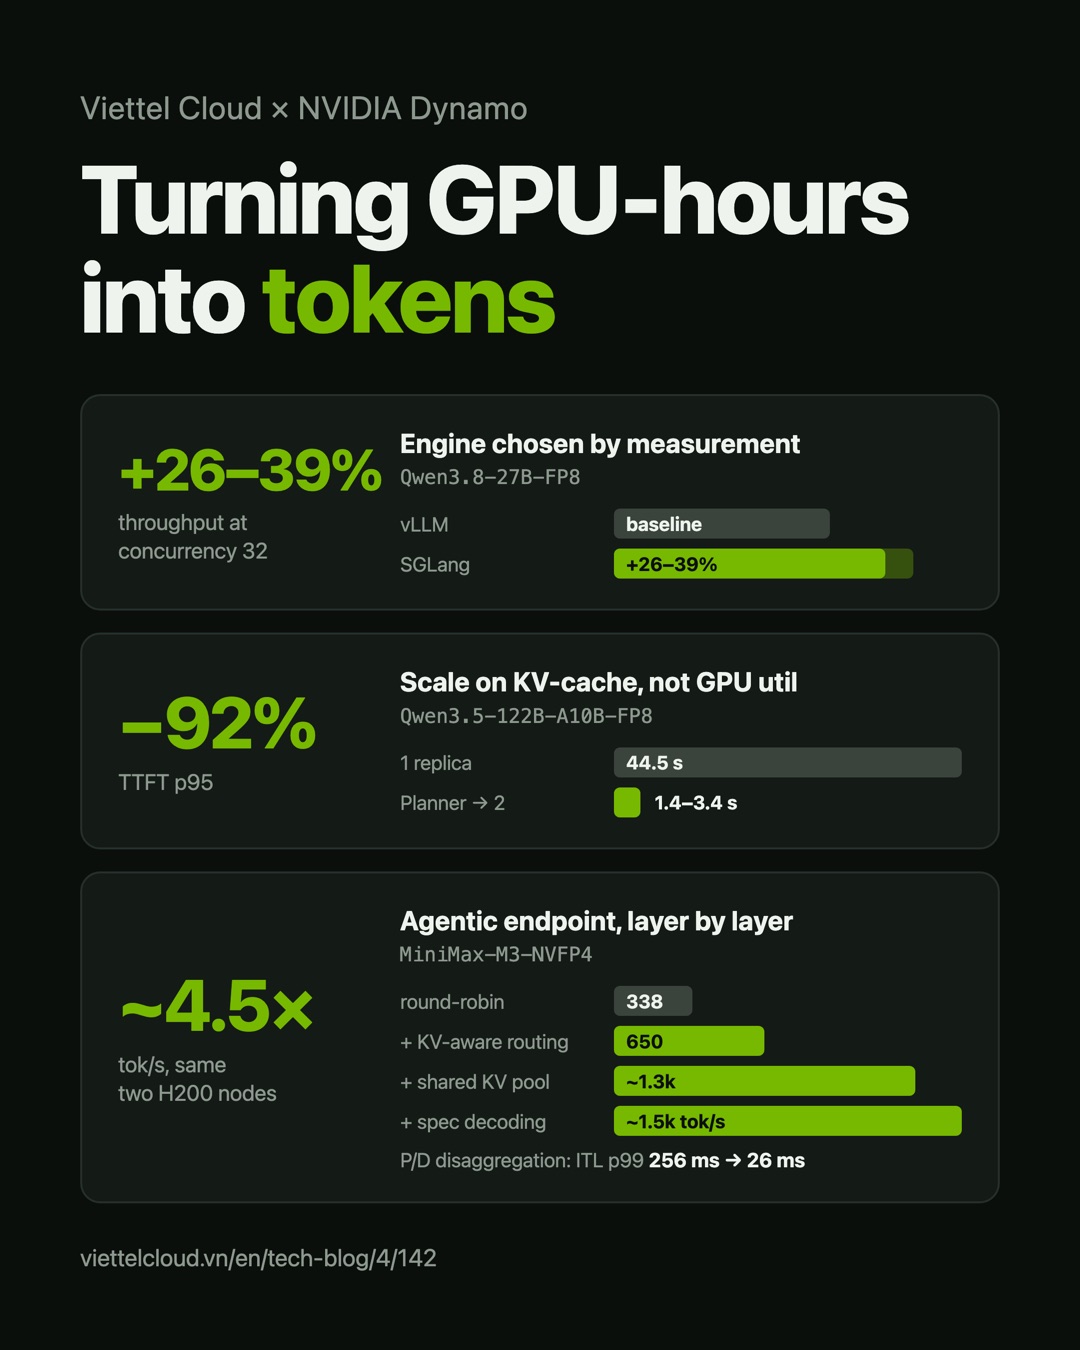
The models were never the problem. Every GPU-hour we lost, we lost in the serving layer above the engine. Results from our fleet:
- Engine chosen by measurement: on Qwen3.8-27B-FP8, SGLang gave 26-39% more throughput than vLLM at concurrency 32
- Autoscaling on KV-cache utilization instead of GPU utilization: TTFT p95 dropped from 44.5 s to 1.4-3.4 s
- Agentic endpoint on MiniMax-M3-NVFP4: ~4.5x throughput on the same 2 H200 nodes, and ITL p99 from 256 ms to 26 ms with prefill/decode disaggregation
If you run several model families on one fleet, we’d like to compare notes.
Full post on the Viettel Cloud Tech Blog, and the listing in NVIDIA Dynamo External Publications.